Ask Cat › AI Tool Summary › Groq
[Special] Groq's Free Tier Caps the 70B and GPT OSS 120B Models at 1,000 Requests a Day
- Free tier: There is
- Cheapest paid plan: US$0/mo and up
- Free quota: The Free Plan needs no card and each model has its own per-minute and …
- Last checked: 2026-10-06
Article last updated: 2026-10-05
Groq sells speed. Its custom LPU chips (its own purpose-built chips for running AI models, not the chips Nvidia or AMD make) push open-source models like Llama and GPT OSS at hundreds of tokens per second — tokens being the word-fragments a model reads and writes, and the usual way AI usage gets measured and billed. Developers hear “fastest inference” and assume the free tier is just as generous. It isn’t. Groq’s free tier requires no credit card, but once you look at the per-model request caps, two of its most-used models — Llama 3.3 70B Versatile and GPT OSS 120B — are stuck at 1,000 requests a day. The smaller Llama 3.1 8B Instant gets over 14 times that. Same free tier, wildly different ceiling, depending entirely on which model you call.
This matters because Groq markets itself on raw speed, not on free-tier generosity. If you’re building something that calls the 70B model more than roughly once every 86 seconds around the clock, you’ll hit the wall before lunch.
What’s actually free, and what isn’t
Groq’s free plan hands out an API key (the credential your code uses to call the model, no human login step after that) the moment you sign up. No card required. But the limits aren’t one number — they’re a grid, one row per model, covering requests per minute, requests per day, tokens per minute, and tokens per day:
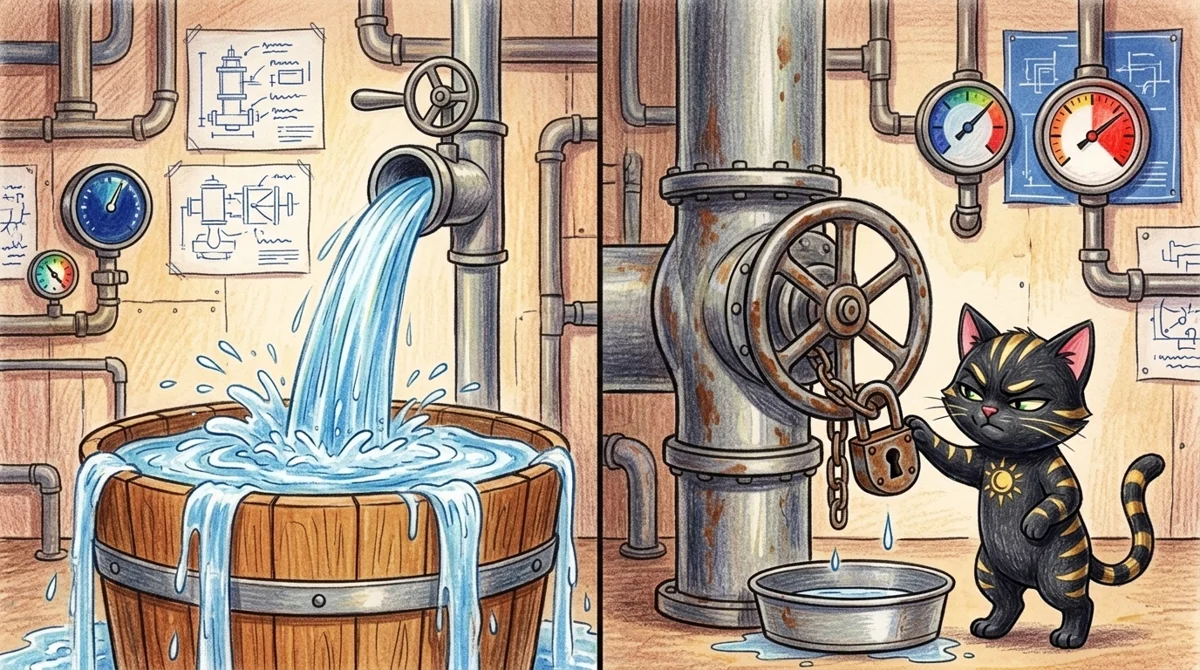
Illustration: While lightweight models enjoy a rushing torrent of free requests, powerful large models are throttled to a locked trickle.
- Llama 3.1 8B Instant: 30 requests/minute, 14,400 requests/day, 6,000 tokens/minute, 500,000 tokens/day
- Llama 3.3 70B Versatile: 30 requests/minute, 1,000 requests/day, 12,000 tokens/minute, 100,000 tokens/day
- GPT OSS 120B and GPT OSS 20B: 30 requests/minute, 1,000 requests/day, 8,000 tokens/minute, 200,000 tokens/day
- Groq Compound: 30 requests/minute, 250 requests/day, 70,000 tokens/minute
- Whisper Large V3 (speech-to-text): 20 requests/minute, 2,000 requests/day, 7,200 audio-seconds/hour, 28,800 audio-seconds/day
Run past any of these and the API returns HTTP 429 — the standard “you’ve been rate-limited, stop sending requests” error. One detail worth knowing: if your request hits a cached result (Groq reusing a previously processed chunk of input instead of recomputing it), those cached input tokens don’t count against your cap. That can stretch a thin daily quota further if your traffic repeats similar prompts.
Figure: groq.com official page, captured 2026-10-05.
Why the small model gets so much more room
The pattern isn’t random. Llama 3.1 8B Instant is the cheapest, lightest model Groq runs, so Groq can afford to let free users hammer it — 14,400 requests a day is enough for most hobby projects and small demos. The 70B and GPT OSS 120B models cost more compute per call, so the free allowance drops to 1,000 requests a day, flat, regardless of how light each individual request is. Groq Compound (its agentic, multi-step tool-calling model) gets squeezed even further to 250 requests a day, because each “request” there can trigger several internal model calls.
The practical read: Groq’s free tier is built for testing and prototyping, not for running a live product on the 70B or GPT OSS 120B models. If your app depends on those and gets real traffic, you’ll bump into the ceiling within hours, not weeks.
What it costs once you outgrow free
Groq bills everything else by the token — pay only for what you process, no seats (per-user license slots) and no monthly minimum. Prices per million tokens, separated into input (what you send) and output (what the model generates):
- Llama 3.1 8B Instant: US$0.05 input / US$0.08 output, running at roughly 840 tokens per second
- GPT OSS 20B: US$0.075 input / US$0.30 output, roughly 1,000 tokens per second
- GPT OSS 120B: US$0.15 input / US$0.60 output, roughly 500 tokens per second
- Llama 3.3 70B Versatile: US$0.59 input / US$0.79 output, roughly 394 tokens per second
Two ways to cut that bill further: Groq’s Batch API (submitting a pile of requests for non-urgent, asynchronous processing instead of one at a time) cuts the cost in half, and any input tokens that hit the cache are billed at half price too. If you use Groq’s built-in tools — web search, page browsing, or code execution — those are metered separately: search runs US$5 to US$8 per 1,000 searches, browsing a webpage is US$1 per 1,000 pages, and running code costs US$0.18 per hour.
What you won’t find on Groq at any price: GPT-5 or Claude. Groq only runs open-source models — Llama, GPT OSS, and a handful of others. If your workflow needs a closed frontier model, Groq isn’t the place, free or paid.
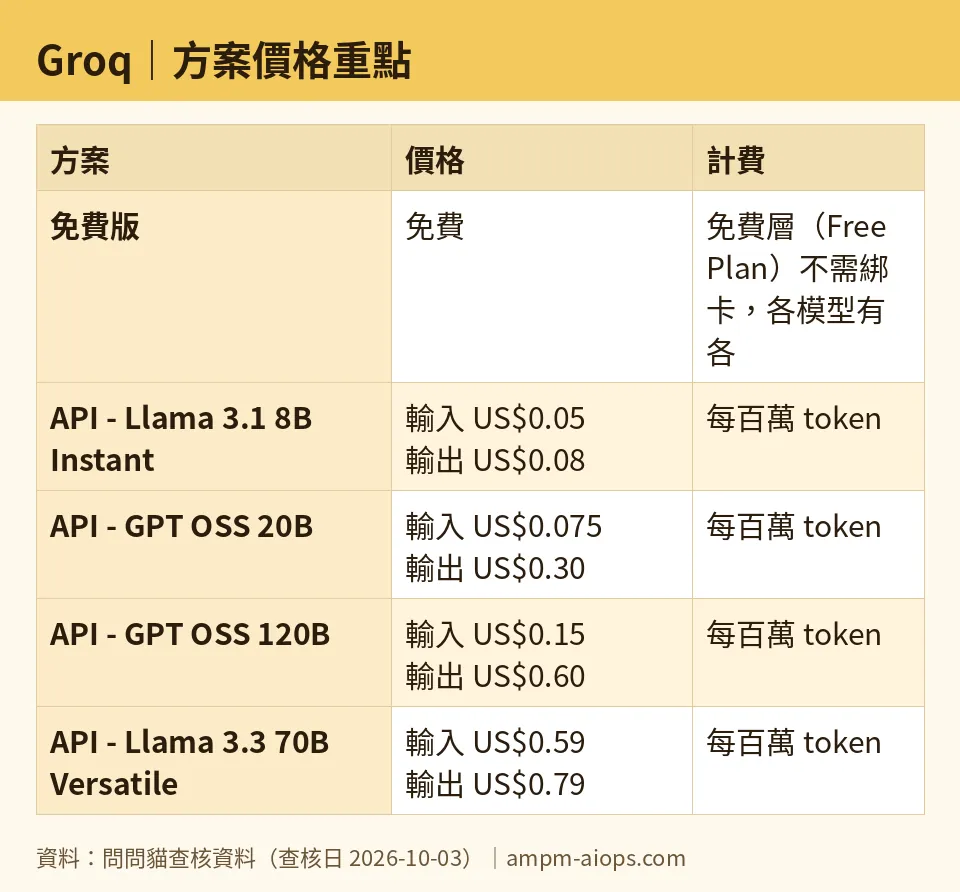
Figure: compiled by AMPM from its verified data (last verified 2026-10-03).
🔍 AMPM exclusive check
Here’s the gap: Groq’s public pricing page (groq.com/pricing) lists per-token costs for paid use, but it does not publish the free-tier rate limits anywhere on that page. The actual numbers — the 1,000-requests-a-day cap on the 70B and GPT OSS 120B models, the 14,400-a-day allowance on the 8B model, the 250-a-day limit on Groq Compound — only show up in the developer documentation at console.groq.com/docs/rate-limits, which we read directly on 2026-08-09. A developer who only checks the marketing pricing page would have no idea the free ceiling varies by more than 14x depending on which model they call.
We also confirmed the cached-token exemption is real and documented: tokens served from cache don’t count against either the per-minute or per-day caps, on any model. That’s a meaningful detail for anyone trying to stretch a 1,000-request daily budget on the 70B model, and it’s also missing from the pricing page — you only find it in the rate-limits documentation, not in the sales copy.
☀️ AMO, the budget-minded cat
AMO’s question is always the same: is free enough, or is paying worth it? For Groq, the answer splits hard by model. If you’re testing on Llama 3.1 8B Instant, free is genuinely enough for a lot of real use — 14,400 requests a day and 500,000 tokens a day covers a small chatbot, a side project, or a classroom demo without ever reaching for a card. AMO would stay on free here.
But switch to Llama 3.3 70B Versatile or GPT OSS 120B for better reasoning, and free drops to 1,000 requests a day — easy to burn through in an afternoon of active development, let alone production traffic. At that point paying is cheap enough that AMO wouldn’t hesitate: the 70B model runs US$0.59 per million input tokens and US$0.79 per million output tokens, and GPT OSS 120B is even less at US$0.15 input / US$0.60 output. For most individual developers, a few dollars of pay-as-you-go usage buys far more headroom than fighting a 1,000-request daily wall. AMO’s verdict: stay free on the small model as long as it does the job, but don’t try to force a serious 70B or 120B workload through the free tier — the math to pay is too favorable to resist, especially with Batch API halving costs further.
Verdict: who should use it, who should skip it
Use Groq if speed is your actual bottleneck and you’re fine running open-source models. The inference speeds — up to roughly 1,000 tokens per second on GPT OSS 20B — are hard to match elsewhere, and the paid pricing is low enough that even moderate production use stays cheap. It’s also a solid free option for prototyping on the 8B model, where the daily allowance is generous.
Skip it if you need GPT-5, Claude, or any closed frontier model — Groq simply doesn’t offer them. Also skip relying on the free tier for anything beyond light testing on the 70B or GPT OSS 120B models; 1,000 requests a day sounds like a lot until a real user base starts calling your app, and the wall arrives fast and without warning beyond an HTTP 429 error.
Written: 2026-10-05 Price last verified: 2026-10-03 Tool last health-checked: 2026-10-05
🔗 Related on AMPM
📎 Sources
All prices and quotas in this article come from AMPM’s verified dataset for Groq (last verified 2026-10-03); primary sources:
🐾 Meet the cats: AMO and PIMI

AMPM is a Taiwan-based AI-tool pricing watchdog. Our motto: ask before you subscribe. Two cats argue every tool from two sides:
- ☀️ AMO — the budget-minded cat. Always asks: is the free tier enough, and is paying actually worth it?
- 🌙 PIMI — the performance-minded cat. Cares about whether it works well, fast, and gets your job done.

When they are done arguing, you know whether to pay. Every number is checked by us, with the verification date at the end.
🐾 Our sister sites also checked
Let's take a look at these
- Groq Comprehensive Introduction: Pricing, Features, and Actual Limitations
- Groq Is the free quota enough?
- Groq Alternatives
- Comprehensive Free Quota List for All Tools